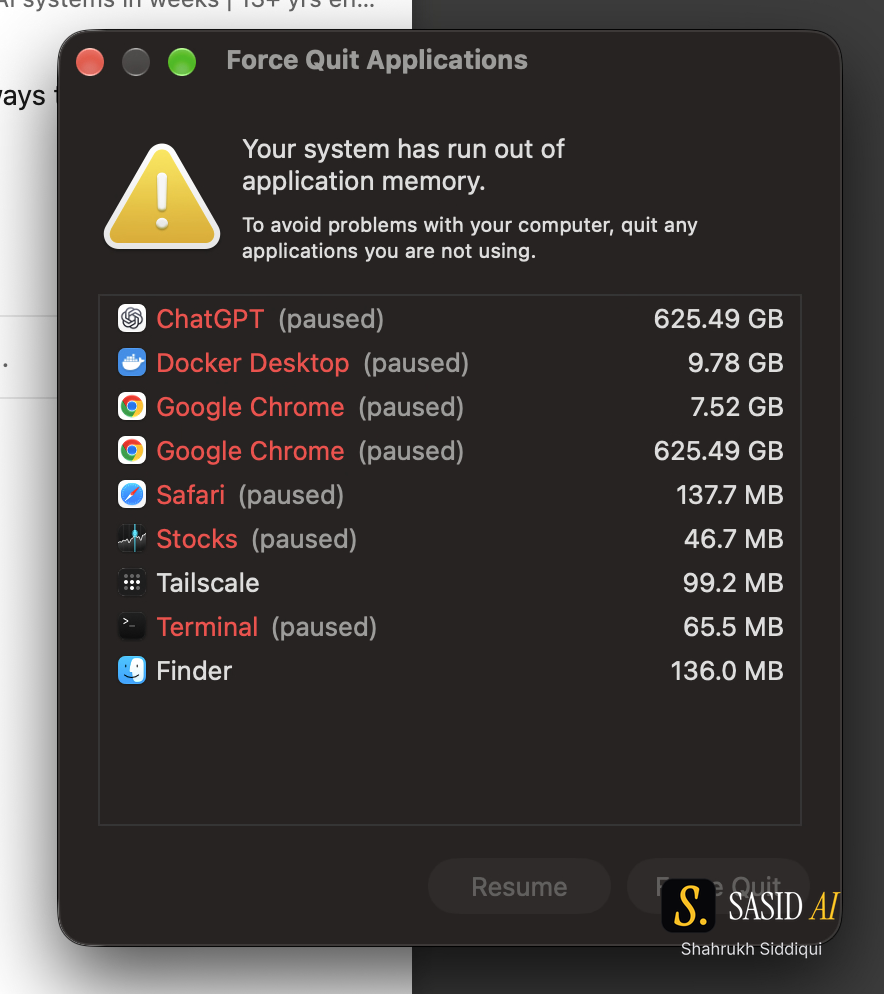
Owner screenshot. macOS dialog-reported values; not a physical RAM measurement.
What Happened
I bought an M3 Ultra Mac Studio so my agents and parallel projects could keep running in the background while I manage everything from my MacBook. On October 8, 2026, during my ChatGPT/Codex work with Chrome open, that setup ground to a halt. macOS showed: "Your system has run out of application memory." My work had already stopped.
The screenshots are real and unedited apart from a SASID watermark and the black redaction of my serial number that was in the original. I did not use generated evidence.
Reading the Dialog Carefully
The dialog lists ChatGPT at 625.49 GB and one Chrome entry at the same figure. Those are the values the dialog reported. They are larger than the machine's memory, so they cannot be measured physical RAM. I do not know what the numbers represent, and I am not diagnosing a leak, a kernel issue or anyone's intent.
Some limits on what the evidence shows:
- The warning labels ChatGPT. It does not identify a separate Codex process.
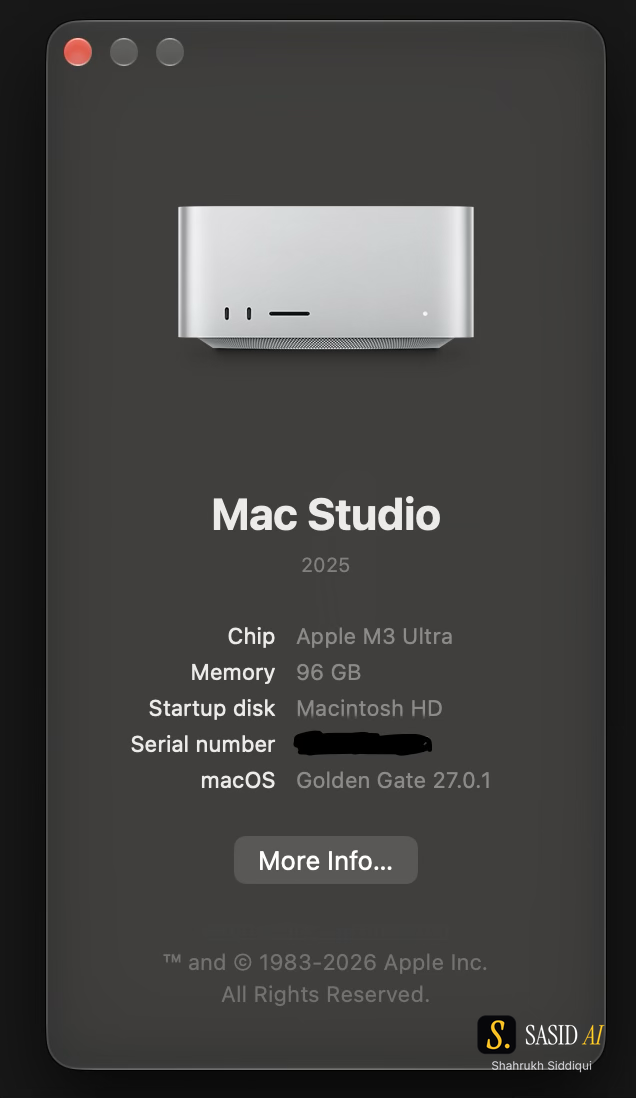
- The About This Mac screenshot shows a 2025 Mac Studio with an Apple M3 Ultra and 96 GB of memory. It does not show Apple's maximum configuration, and I am not claiming more memory would have prevented this.
- That my work stopped is my report. No benchmark or root cause was captured.
Why This Matters for Agent Setups
The lesson I took away is about where the limits are. When people plan AI work they consider model capability and subscription limits. A third constraint sits underneath: the machine and its apps. Agents that run for hours on a workstation share it with a browser, desktop apps and whatever else is open.
When a limit hits, you want predictable behavior:
- Isolation. Keep long-running agent work separate from interactive browsing where you can, whether by user account, a dedicated machine or a container.
- Checkpointing. Agents should save progress often enough that a forced quit loses minutes, not a day.
- Recovery. After a restart, can the work resume without a human reconstructing state? Plan for this before it is urgent.
- Visibility. Know what is running and what each piece is using, so a warning leads to a decision, not guesswork.
- Alerts. Decide who or what tells you that background work has stalled.
A Capacity Planning Checklist
Before you size hardware for agent workloads, write down:
- How many agents or sessions run at the same time, at peak.
- Which applications share the machine, and which can be closed or moved.
- How much memory each agent process uses over a long session, measured on your workload.
- Whether any local models run, since they claim large, steady memory.
- What happens on failure: restart policy, resume steps, notification.
- Which tasks justify a second machine instead of a bigger one.
Measure first. Buying more memory is a reasonable answer only once you know what is using it.
What I Am Doing About It
At this point, I care as much about resource limits and reliable recovery as I do about model capability. I want my agents to keep working without my babysitting the machine. I track usage allowances across accounts with a private dashboard, described in the usage meter article, but memory visibility on the machine is a separate problem I am still working on. I have no fix to report.
If you plan to run small decision models locally alongside agents, memory planning matters even more; see the Liquid AI d1 article. The week's other updates are in the October 2–8 recap.
Read Next
The original post is on LinkedIn. For hardware context, Apple's Mac Studio announcement describes the product line; it does not diagnose my warning. The Agent companion, Running agents unattended: resource limits and recovery, covers the operating side of the same event.
If you want background agents designed to checkpoint and recover, our AI agent development service covers that kind of work. Questions can go through the contact page.


