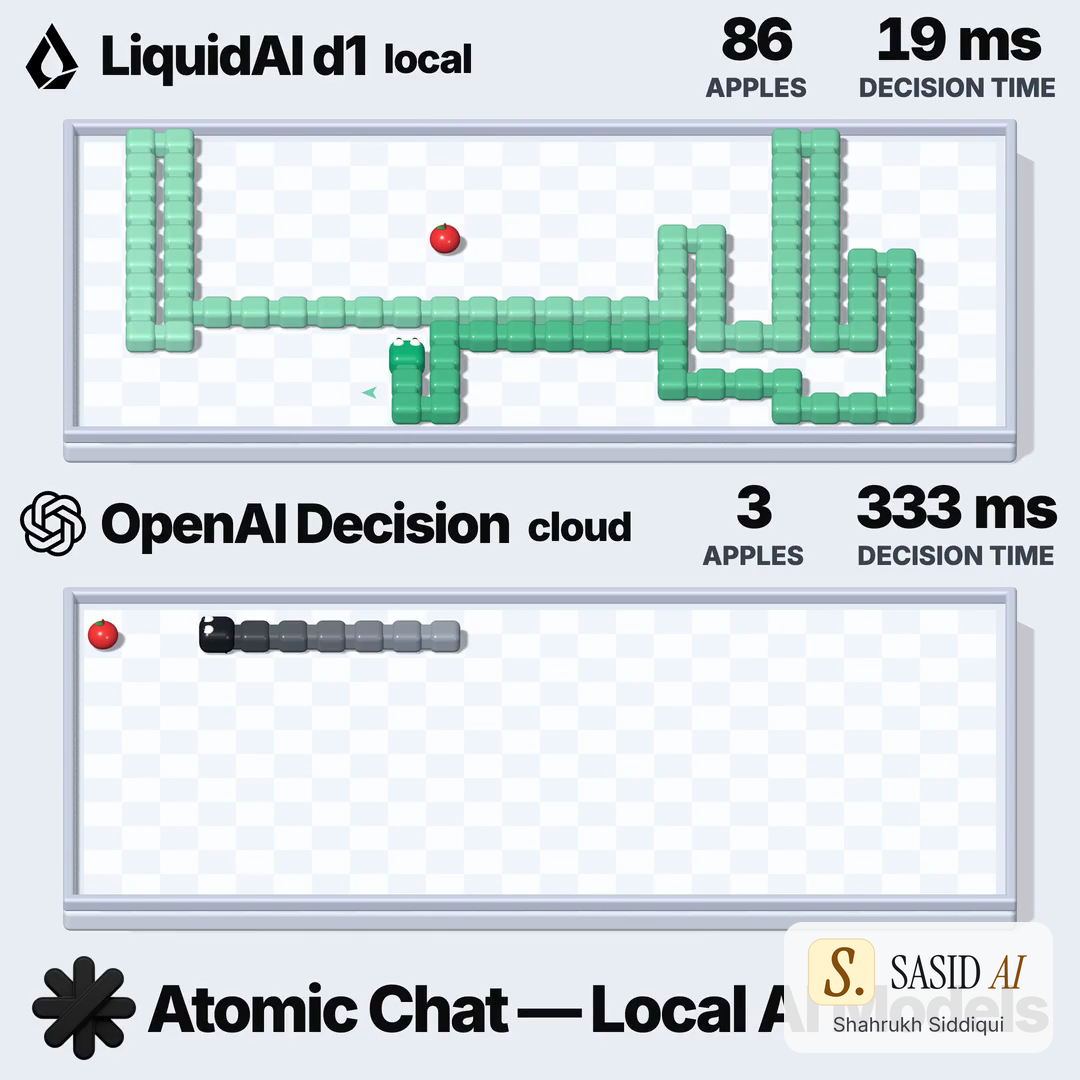
Original atomic.chat demonstration frame. Vendor demo, not our benchmark.
What d1 Is
On October 7, 2026, Liquid AI released open-weight d1-3B. Per the release and the model card, it returns structured decisions in one forward pass with zero output tokens. It is a decision model: you pose a question and it returns a structured choice, without generating text token by token. It is not a chat model and should not be evaluated like one.
Decisions like this appear all over agent workflows: which tool to call, which view to show, whether an output passes a check, which queue a request belongs in. Many of those do not need a long reasoning chain. They need a fast, structured answer.
Reading the Numbers Correctly
Two figures circulate, and they come from different setups.
The 8 ms figure. Liquid AI reports 8 ms for one question on an NVIDIA RTX 4090. The conditions matter: bf16 precision, the median of 20 runs, one request at a time, with compilation and CUDA graphs. That is an inference measurement for a single decision. It is not the latency of a browser, an API, a game loop or an agent doing real work end to end.
The Snake demo. The video by atomic.chat, shared by Liquid AI, compares local d1 with a cloud decision API playing Snake. It ends at 86 apples versus 3 in that particular run. According to its creator, the setup used an RTX 3090, which differs from the 4090 benchmark. It is the creator's demo result, not my measurement and not a universal model comparison. The video keeps atomic.chat's branding, and you can watch the original.
Frame from the atomic.chat demo; the result shown belongs to that run.
Liquid also reports collaboration with NVIDIA on Jetson measurements, which NVIDIA publishes in its Jetson AI Lab guide. That is a statement about platform support. It does not establish NVIDIA funding.
Where a Decision Model Might Fit
I run multiple agents on parallel projects, and each workflow has small decisions inside it. Candidate uses I would try:
- Tool routing. Choosing which of several tools a request needs.
- View selection. Picking a chart or table type, as in the question-shaped interface idea in the Intelligent UI article.
- Output checks. A cheap pass or fail gate before an expensive step.
- Triage. Sorting requests by category or urgency.
Larger models would still handle work that needs deeper reasoning. A decision model would sit in front of or beside them, not replace them.
How I Would Evaluate One
The original post establishes no owner-run installation, integration or benchmark. Here is the evaluation I would propose:
- Collect labelled decisions from your own workflow: inputs and the choice a reviewer judged correct.
- Measure accuracy on those cases, not on a public demo, and break down the failures.
- Compare against your current method. That may be a large model prompt, rules or a classifier.
- Measure the full workflow. Include model loading, data preparation, any fallback to a larger model and the time to handle errors. A fast decision inside a slow pipeline changes little.
- Define a fallback. When confidence is low, route to the stronger model and log it.
- Check the license and hardware. Open weights help, but confirm the terms and run on the hardware you will actually deploy to.
Only after the workflow-level numbers exist would I claim an efficiency gain.
Where This Connects
A decision model pairs naturally with the lead-and-worker idea in the Haiku 5.5 subagent plan, where the open question is also cost and time per accepted result. For the week's wider context, see the October 2–8 recap.
Read Next
The original post is on LinkedIn. Primary sources: Liquid AI's d1 release, the model card and NVIDIA's Jetson guide. The Agent companion, Decision models as agent gates, covers how such a model would be operated and monitored inside an agent system.
If you are considering small models for routing or checking inside an agent, our AI agent development service can help design the evaluation first. You can also reach us through the contact page.


