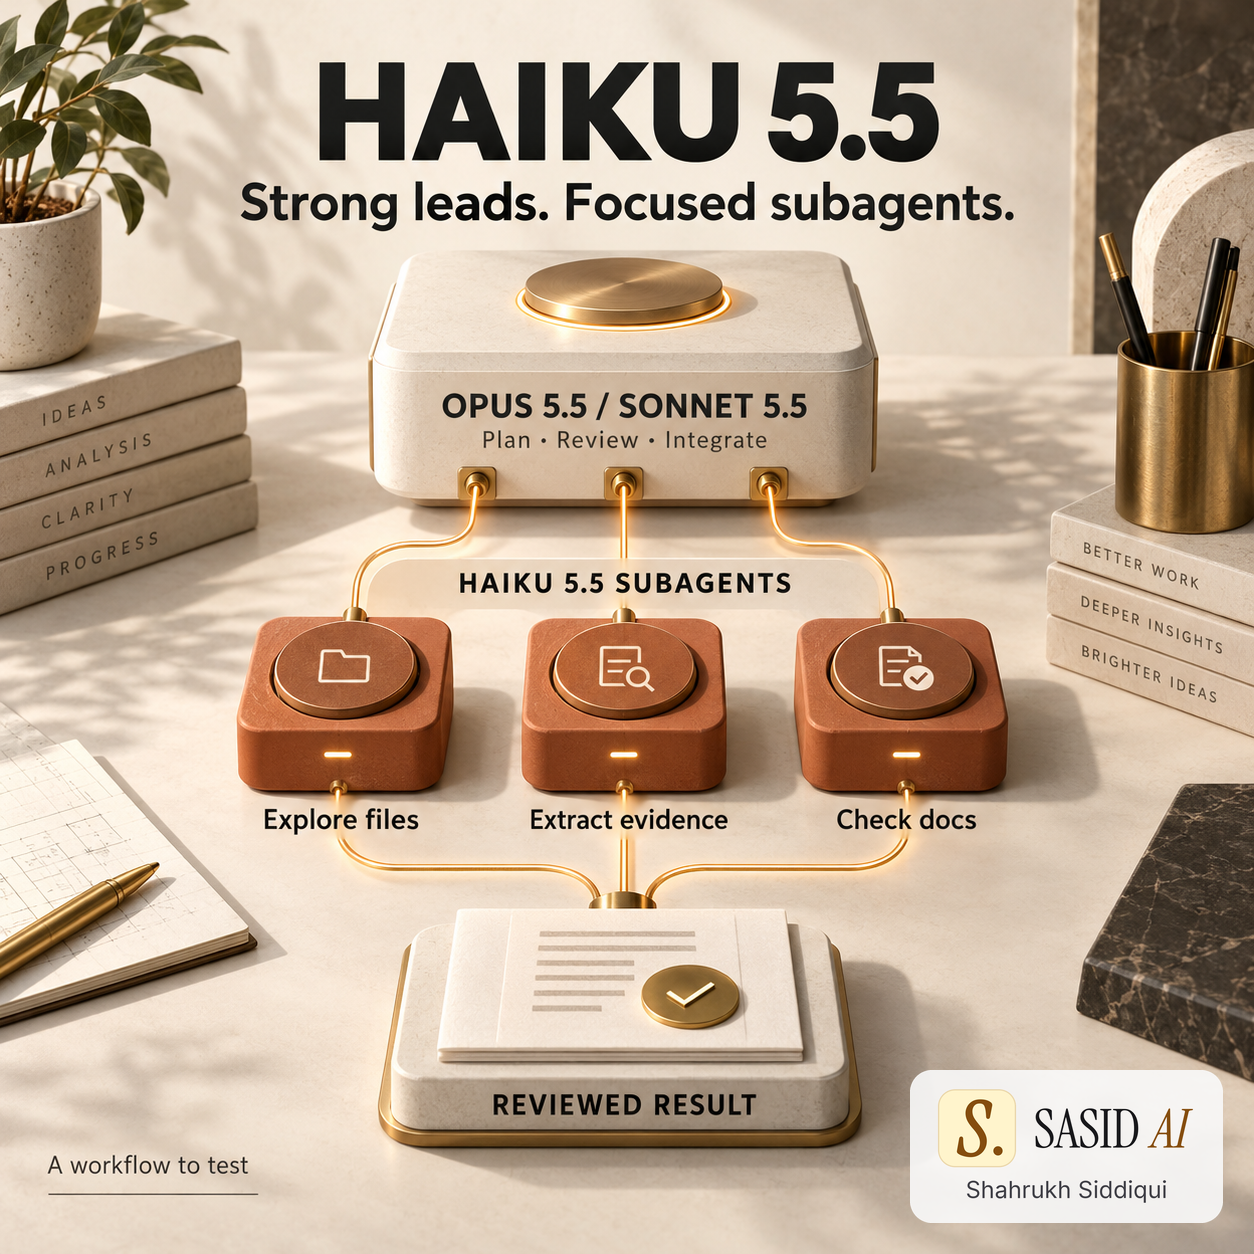
AI-generated editorial illustration; not a screenshot.
What Was Announced, and What Was Not
On October 7, 2026, Anthropic launched Claude Haiku 5.5. In its launch announcement, Anthropic says Haiku 5.5 pairs well with Opus 5.5 and Sonnet 5.5 as a coding subagent, and lists lower API list pricing than the larger models. The same page records a separate change from that week: Sonnet 5.5 cache reads became 50% cheaper.
That is the vendor's positioning and price list. It is not evidence that a mixed team of models finishes your work faster or cheaper. I have not run this setup at scale, and the article below is a test plan, not a result.
The Workflow I Would Test
The shape is a strong lead with bounded workers:
- Lead (Opus or Sonnet 5.5). Plans, makes architecture decisions, reviews and integrates.
- Workers (Haiku 5.5). Explore files, extract facts, check documentation and summarize logs, in parallel.
- Escalation. Ambiguous findings and failed work go back to the lead rather than being retried blindly by the worker.
The hypothesis is simple: spend stronger-model tokens where judgment matters, and give narrow, well-specified tasks to the cheaper model. Claude Code supports this pattern through subagents, which run focused work and report back. One detail from that documentation matters for budgeting: subagent requests are still your requests. On a subscription they draw from the same shared usage limits.
Which Tasks Are Good Worker Candidates
A task suits a worker when its output can be checked cheaply. Use these criteria:
- Narrow scope. One question, one directory, one log file.
- Clear output shape. A table, a list of file paths, a yes or no with a quote.
- Evidence attached. Ask every result to cite the line or file it came from, so the lead can spot-check.
- Low cost of being wrong. A missed file in an exploration is recoverable. A wrong schema migration is not.
- Independent of other workers. Parallelism only helps when tasks do not need each other's results.
Tasks that fail these tests, such as ambiguous design choices, cross-cutting refactors and security-sensitive review, stay with the lead.
The Metric That Decides It
Per-token price is the wrong yardstick. A cheap call that produces work you reject costs more than it saves. For API workloads I would measure cost and time per accepted change, counting retries, the lead's review time and any rework. For subscription workloads I would also track how much allowance each approach consumes, because that is the real limit.
A practical test design:
- Pick 20 or more representative tasks from your own backlog.
- Run them once with a single strong model and once with lead plus workers.
- Record accepted-or-rejected, wall-clock time, tokens or allowance used, and the number of escalations.
- Compare cost and time per accepted result, including rejected attempts, retries and review; report the acceptance rate separately.
Stop the experiment, or narrow the workers' remit, if escalations eat the savings or if reviewers start trusting worker summaries without checking them.
Hidden Costs to Price In
Delegation has overhead. Writing a precise brief takes tokens. Collecting results into the lead's context takes tokens. If the workers' summaries are long, the lead pays to read them. And any cache pricing change can shift which design is cheaper, so re-run the comparison when list prices move. Where you track usage across several accounts, visibility helps; I describe my own approach in the usage meter article.
For a broader view of how this week's other releases fit together, including decision models for routing, see the October 2–8 recap and the Liquid AI d1 write-up.
Read Next
The original post is on LinkedIn. Primary sources: Anthropic's Haiku 5.5 announcement and the Claude Code subagents documentation. The Agent companion, Haiku 5.5 as a worker in an agent loop, looks at how the same pattern is operated and evaluated inside an agent system.
If you are designing a multi-model agent and want help defining acceptance tests before you commit to an architecture, see our AI agent development service. A short question is also welcome through the contact page.


